My PokéBot can now reliably play through all of Pokémon FireRed. I first wrote about my Pokémon-playing bot back in May, at which point it could complete the first couple of missions from the game. As I emphasised at the time, this was not another 'LLM plays X' experiment; rather it was an opportunity for me to learn how to work with an AI agent for coding, and to explore developing and optimising deterministic macros.
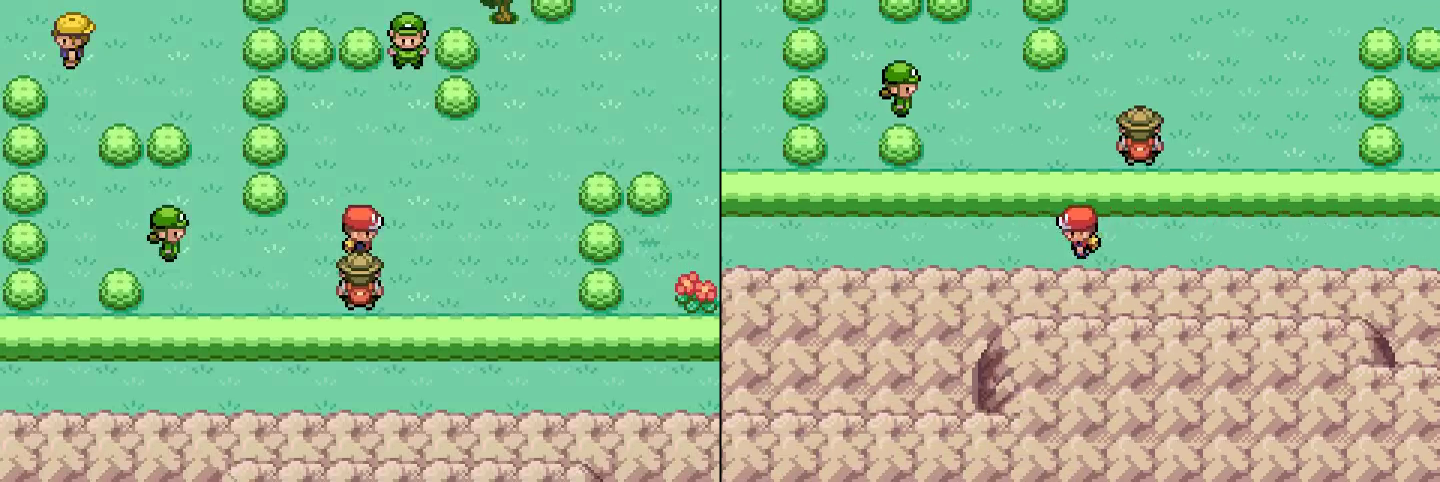
There is no LLM in the loop. It's a Python script that executes actions based on what it 'sees' in the game, triggering general-purpose modules (like 'navigation' and 'battle' algorithms). (Note that these modules are coded 'manually' and are not grown in an online/on-demand way). In fact, "what it sees" is quite limited; it can't actually see the screen pixels, and it only has access to what a player could realistically observe - like on-screen text, nearby tiles, etc. In a few very tricky cases we pre-calculated the moves it should make (e.g. move to a specific tile to trigger a certain interaction) but mostly it's just a bunch of heuristics and calculations which dictate what should happen next (for example - deciding which moves to make in a battle based on the opponent's HP). Its main control loop is a fixed sequence of storyline missions (beat Brock, beat Misty, etc.) which break down into sub-goals (e.g. buy potions, catch Mewtwo). But quite a lot of interesting behaviour can emerge from heuristic algorithms - for example the bot is set to backtrack efficiently through all previously-seen Pokémon in order to hit a threshold of 50 total catches, and this leads to a different set of targets each time. I also particularly enjoyed seeing the navigator function organically find this shortcut on its way back after a particularly maze-like route.
It would be really interesting in future to let it dynamically decide its own sequence of missions and goals. But "beat FireRed" as the overall objective is a long-horizon task which requires a certain level of sophistication in the system that solves it. I imagine that one could represent the missions and sub-goals as a hierarchical task network, and then apply a planning system to work out which tasks and actions are required from the bot's current state - and then to optimise so that it does it as fast as possible. Although, given it's not known a priori exactly which task sequences lead to success (e.g. do we train Pikachu to level 99 (guaranteed win) or level 20 (possible defeat and retry) to fight an upcoming battle; and which choice leads to success in the least time overall?) this might involve modelling stochastic decision processes - planning under uncertainty - where the bot needs to model the likely outcomes and costs of its actions, execute them, observe the results, and re-plan. From here, it's not a huge conceptual leap into full-blown RL, which could also be a future experiment.
But none of this happens in the current bot. There are so many possibilities for planning a party composition, when to train, when to stop... and it does not feel particularly verifiable. As a result of deferring high-level goal optimisation work, there are some limitations in the bot - most notably the reliance on 'beast mode' which basically maxes my party's stats so that they are guaranteed to win battles. There is also some glitchiness in general gameplay like walking into walls or accidentally closing out of dialogues (which led to a failed Ho-oh catch attempt right at the end of the showcased playthrough..!). This is mostly due to race conditions between reading game state and taking actions (which I feel could be solved by having a cleaner observe-then-act architecture throughout the system).
Nonetheless, I'm happy with the progress, and learned a lot first-hand about agentic coding through the process, including tips like:
- Set up your harness to notify when it needs attention, so you can kick off big
/goalloops - Establish clean primitives, then agents are less likely to make weird decisions and write slop
- When an agent can't see the screen (or more generally verify the application it's building), it will confidently misinterpret the root causes of errors
There is something very cool about pressing a button and seeing a bot start interacting with a game in a (relatively) human-like way - like navigating menus and solving mazes without being told the solution beforehand - and it's even more rewarding when you can come back multiple hours later to see it still making progress.
In fact, I found it so uncanny to watch the bot in action that, inspired by "Lara Croft AI plays Tomb Raider", I gave Qwen access to the bot logs and let it narrate the full playthrough (Qwen narrating ~22 hours of logs cost <$2, and Pocket TTS was free). It gets a bit cocky at times, but it does add another layer of personality to the simulacrum.